CarouselMachine Learning
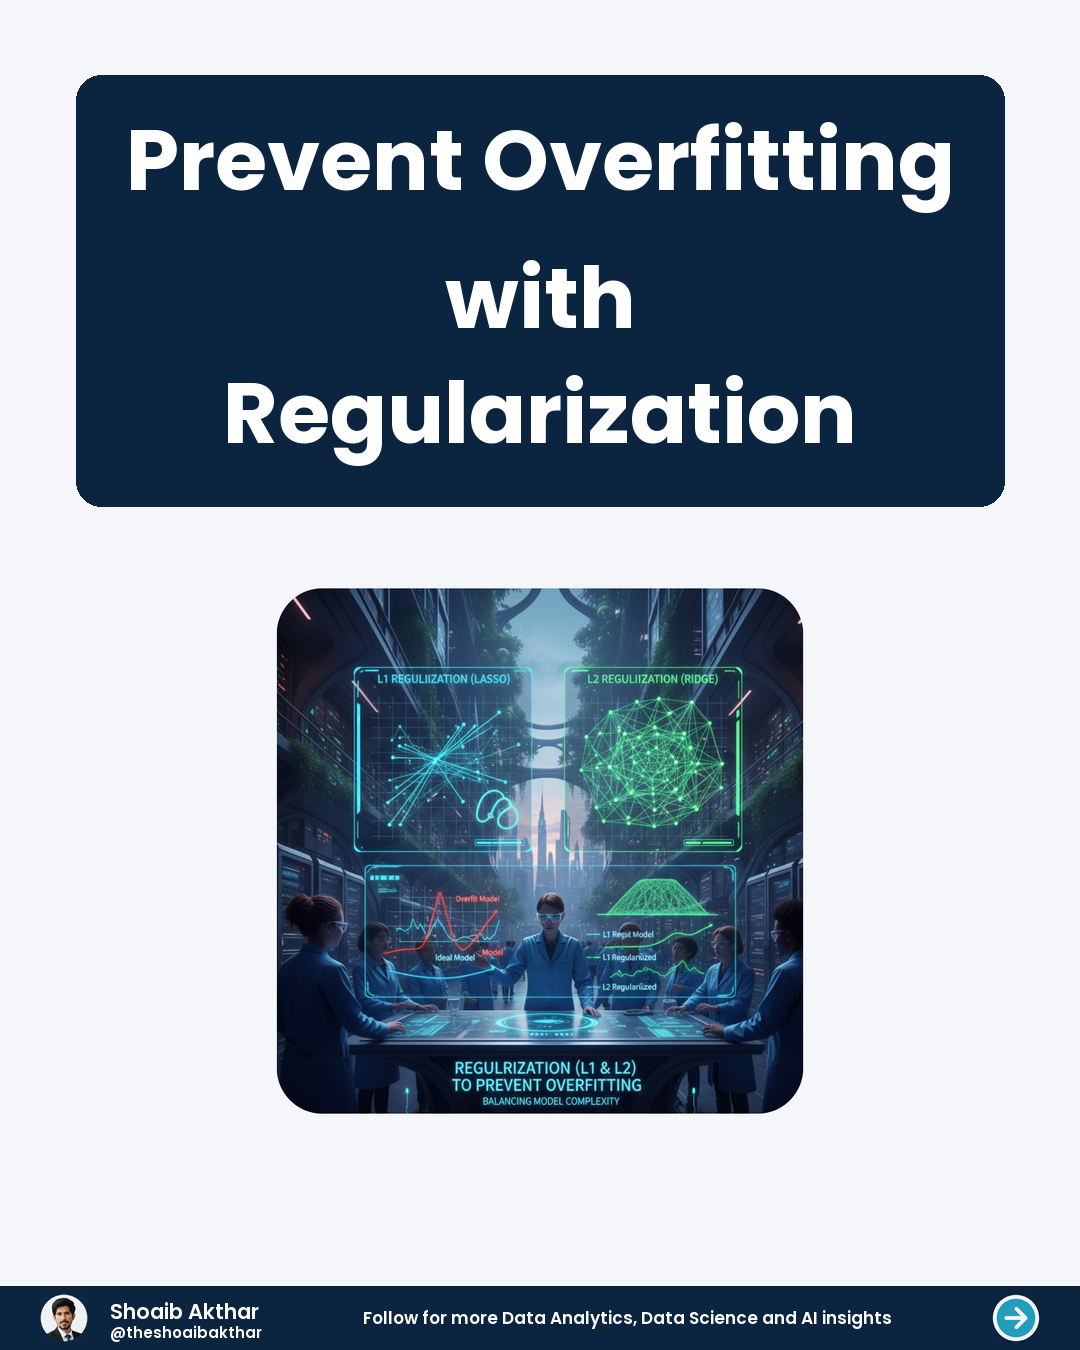
Prevent Overfitting with Regularization
Overfitting happens when our model learns the training data too well. It memorizes noise and specific details instead of general patterns.
 1 / 10
PDF not showing? Open it in a new tab.
Read it as text
The full carousel content, slide by slide.
01What is Overfitting?
- Overfitting happens when our model learns the training data too well.
- It memorizes noise and specific details instead of general patterns.
- This leads to poor performance on new, unseen data.
- The model fits the training data perfectly, but doesn’t generalize.
- A model that is too complex can overfit.
02Introducing Regularization
- Regularization is a technique to simplify a model.
- It adds a penalty to the model's complexity.
- This encourages the model to learn simpler, more general patterns.
- Essentially, it prevents the model from fitting the training data too closely.
- Regularization helps to avoid overfitting.
03L1 Regularization
- L1 regularization (Lasso) adds a penalty proportional to the absolute value of the coefficients.
- It can drive some coefficients to exactly zero.
- This leads to feature selection – the model effectively ignores irrelevant features.
- Useful when you suspect many features are redundant.
- Regularization helps create more interpretable models.
04L1 Regularization Effects
- Sparse model: Many coefficients are zero.
- Feature selection: Irrelevant features are ignored.
- Simplified model: Easier to understand and interpret.
- Dimensionality reduction: Reduces the number of features.
- Can be computationally expensive with large datasets.
05L2 Regularization
- L2 regularization (Ridge) adds a penalty proportional to the square of the coefficients.
- It shrinks coefficients towards zero, but rarely sets them to zero.
- This prevents any single feature from having too much influence.
- Generally preferred when you have multicollinearity.
- Less prone to feature selection than L1.
06L2 Regularization Effects
- Coefficient shrinkage: Coefficients are reduced.
- Prevents overfitting: Keeps complex models simpler.
- Suitable for multicollinearity situations.
- Doesn't perform feature selection.
- Computationally efficient, even with large datasets.
07Combining Regularizations
- Sometimes, combining L1 and L2 regularization is beneficial.
- This is called Elastic Net regularization.
- It combines the features selection of L1 with the coefficient shrinkage of L2.
- Can be a powerful approach for complex datasets.
- Requires tuning of both penalty parameters.
08Choosing the Right Approach
- The choice of regularization technique depends on your data and model.
- L1 is good for feature selection.
- L2 is good for preventing overfitting in the presence of multicollinearity.
- Experiment with different regularization strengths.
- Cross-validation is essential for tuning regularization parameters.